
Writing
Everything I've written, newest first. some of it I'd still stand behind.
2026
 Healthcare integration10 min readStop Polling the EHR: FHIR Subscriptions and Event-Driven AI AgentsWake healthcare AI agents on EHR event notifications: FHIR Subscriptions, webhooks or HL7v2, id-only payloads, gap detection, debounce and audit.
 Data platforms12 min readAI Business Process Mapping Should Output a Graph, Not a DiagramAI process mapping that holds up: LLM extraction into a typed graph, source spans, measured alias merges, owner sign-off and HL7 event log checks.
 Applied LLMs & AI engineering7 min readAI Forward Deployed Engineer Agent: Its Riskiest Output Is a DefaultAn AI forward deployed engineer agent scaffolds a partner integration in minutes. Its riskiest output is the business rules it fills in as defaults.
 Healthcare integration10 min readIs Text Messaging HIPAA Compliant? Only With a Gate Before send()Is texting patients HIPAA compliant? Only with no PHI or a warned patient who asks. Who needs a BAA, why carriers usually don't, and the gate before send().
 Healthcare integration8 min readLLM Decision Support Without Alert Fatigue: Make the Hook Say NothingLLM CDS without alert fatigue: keep the model out of the 500 ms hook path, dedup per encounter, ask for quiet cards, and cite FHIR or say nothing.
 Applied LLMs & AI engineering8 min readAI Draft Replies to Patient Messages: Route, Ground, MeasureAI draft replies to patient messages work when you route first, ground drafts in FHIR, measure edits and discards by category, and never let the model send.
 Applied LLMs & AI engineering10 min readDetecting Model Drift in Clinical AI: Your Labels Won't Tell You in TimeDetect model drift in clinical AI without labels: override and edit rates, FHIR input checks, pinned models, frozen eval replays, and preset alert actions.
 Healthcare integration8 min readHow to Format FHIR for an LLM: Same Patient, Different Med ListSame patient, three renderings, three med lists. How to pick a FHIR format for an LLM by task, plus a benchmark harness for the edge cases that break it.
 Healthcare integration11 min readHTI-5 Drops the AI Model Card From Decision Support. Ship Your Own.HTI-5 would drop the 31 model card attributes from decision support. Ship them yourself: a versioned model card, CDS Hooks links, Provenance, local validation.
 Healthcare integration9 min readEpic Agent Factory Will Eat the Easy AI. Build What It Can't.Epic Agent Factory vs custom build: which healthcare AI it replaces, what stays outside it, and how to plug into Epic with CDS Hooks, SMART and FHIR.
 Healthcare integration10 min readDe-Identifying Clinical Notes for LLMs: Your Overall Recall Number Is LyingPHI redaction for LLMs: score recall per Safe Harbor identifier, gate MRN and SSN at 100%, and choose a date policy on purpose.
 Healthcare integration8 min readClaude Code for FHIR and HL7v2: The Agent Doesn't Get to Say DoneClaude Code can write FHIR and HL7v2 interface code. A verification loop decides done: FHIR Validator, replay diffs, terminology checks, PHI hooks.
 Data platforms8 min readNeo4j vs Memgraph: Neither Should Be Your Source of TruthNeo4j vs Memgraph from someone who moved Graphite Atlas twice: why we left Neo4j, the Memgraph outage, real pricing, and why Postgres should hold the truth.
 9 min readHL7v2 to FHIR Conversion With an LLM: Mapping, Not MessagesUse an LLM for HL7v2 to FHIR mapping at design time, never on live messages. Real bugs, a diff-and-validate loop, and how to catch feed drift.
 8 min readWriting AI Notes Back to Epic: FHIR on the Outside, Vendor-Specific on the InsideWriting AI scribe notes back to Epic, Oracle and eCW via FHIR DocumentReference: payloads, silent failures, audit trails, and why the model never signs.
 Applied LLMs & AI engineering10 min readLLM ICD-10 Coding Accuracy: Why the Model Shouldn't Type the CodeGPT-4 scored 33.9% on ICD-10-CM code lookup. Don't let the model type the code: retrieve from the code set, check rules in code, cite the note.
 11 min readHow to Detect Hallucinations in AI Clinical Notes Before They're SignedSplit the note into claims, cite each to a FHIR resource, and reject empty or truncated output before a clinician signs.
 Healthcare integration9 min readSMART Backend Services for AI Agents: system/ Scopes Are God ModeSMART Backend Services gives an AI agent every patient the client policy allows. Borrow a clinician's token instead, and trace chart reads to a model run.
 9 min readIs Claude Code HIPAA Compliant? Covered Isn't Compliant.Claude Code fits under Anthropic's BAA only in narrow setups, and that never makes your app compliant. What's covered, ZDR vs HIPAA config, where PHI leaks.
 8 min readThe Best FHIR MCP Server Gives the Model No FHIR ToolsWhy a production FHIR MCP server gives the model typed tasks, not FHIR: SMART scopes, Bundle bloat, minimum PHI and audit logs from MedScrub and eSpiral.
 9 min readCMS-0057-F FHIR Prior Auth API for 2027: Keep the LLM Out of Order-SignCMS-0057-F makes FHIR prior auth APIs due in 2027. How CRD rides CDS Hooks, why no LLM belongs in order-sign, and where AI can safely draft DTR answers.
 Applied LLMs & AI engineering8 min readFDA's 2026 Clinical Decision Support Guidance Didn't Bless Generative AIFDA's 2026 clinical decision support guidance is silent on generative AI. What changed, and how to build LLM CDS clinicians can independently review.
 Applied LLMs & AI engineering7 min readYour Support Team Is Claude Code on a TimerAn L2 support engineer that's just Claude Code on a /loop, with all its state living in Slack reactions. No app, no database, no deploy — and it only pings you when it's real.
 Applied LLMs & AI engineering4 min readWhat an AI Audit Actually FindsMost teams asking for AI don't have a model problem. They have a "which problem is even worth it" problem. Here's what a real AI audit surfaces — and why "don't build this" is often the most valuable line in the report.
 Applied LLMs & AI engineering24 min readInside a Production Voice Agent: How the Stack Actually ShipsProduction voice-AI has converged on a pattern: graph-based conversations, separated decision and response prompts, synthetic-call regression testing, and per-component latency budgets. Why the stack looks the way it does — and what most teams are still missing.
 Applied LLMs & AI engineering19 min readPrompt Engineering Didn't Die. It Got Unrolled.Everyone keeps announcing the death of prompt engineering. They are describing the symptom, not the shift. The loops you used to run by hand — refine, retry, verify, learn — moved out of your head and into infrastructure. Four of them, simultaneously.
 Engineering leadership & career10 min readThe Two Rhythms of B2B Tech: What Palantir Gets Right That Most Companies Get WrongPalantir built a company on the idea that software alone isn't enough: you need engineers embedded with customers. That model has a name, a cost, and a hidden technical debt time bomb most B2B companies are quietly sitting on.
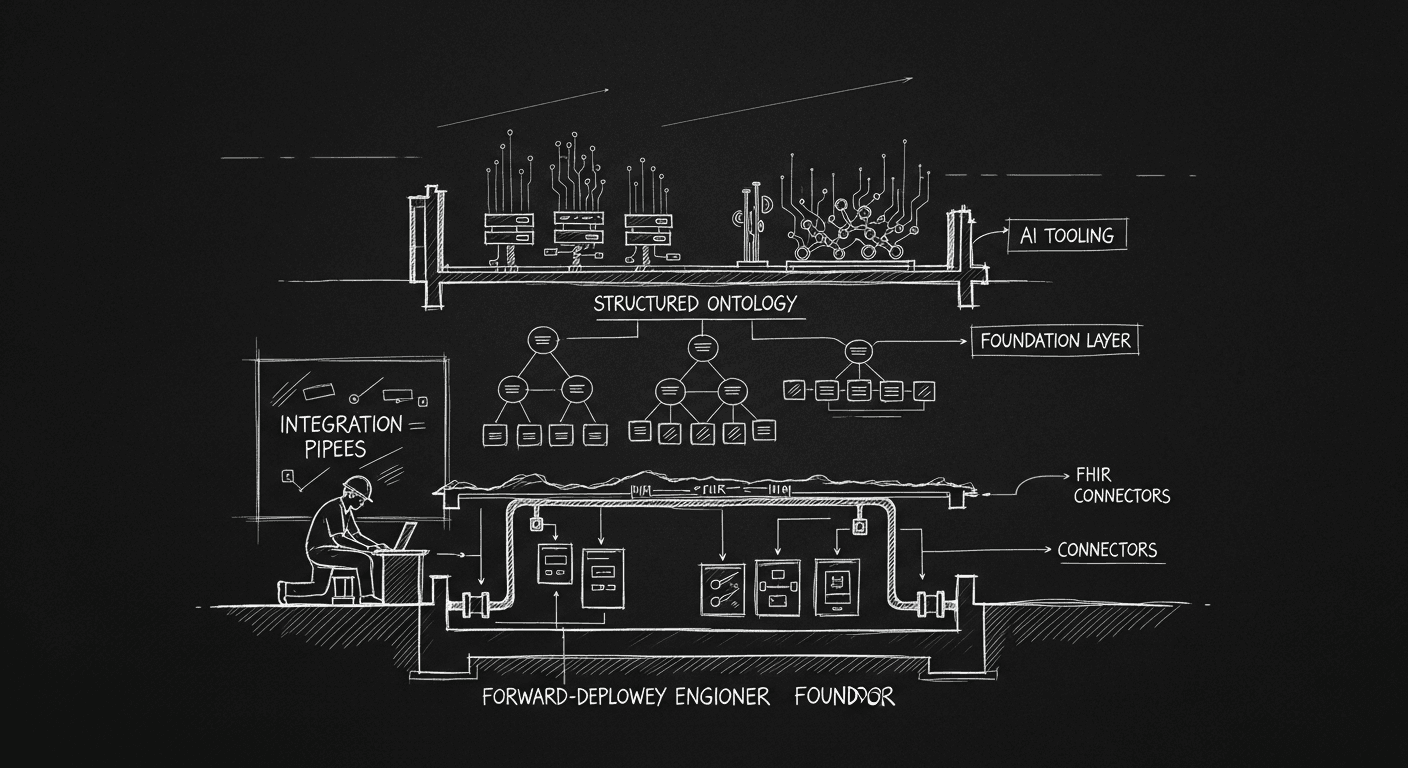 Applied LLMs & AI engineering8 min readHealthcare AI Will Be Won by Verticals. The Recipe Has Been Around for a Decade.Most healthcare AI companies are failing for the same reason. The ones winning are running the same playbook: one Palantir figured out before anyone called it AI. Forward-deployed engineer. Ontology. Integrations. Then AI tooling.
 Applied LLMs & AI engineering7 min readPenpal: Dispatch Tool Today, RPG Interface TomorrowI built a tool that turns GitHub issues into pull requests using a three-agent pipeline. That's the boring part. The interesting part is what happens when you stop thinking about AI agents as productivity tools and start thinking about them as a workforce, and build a world for them to live in.
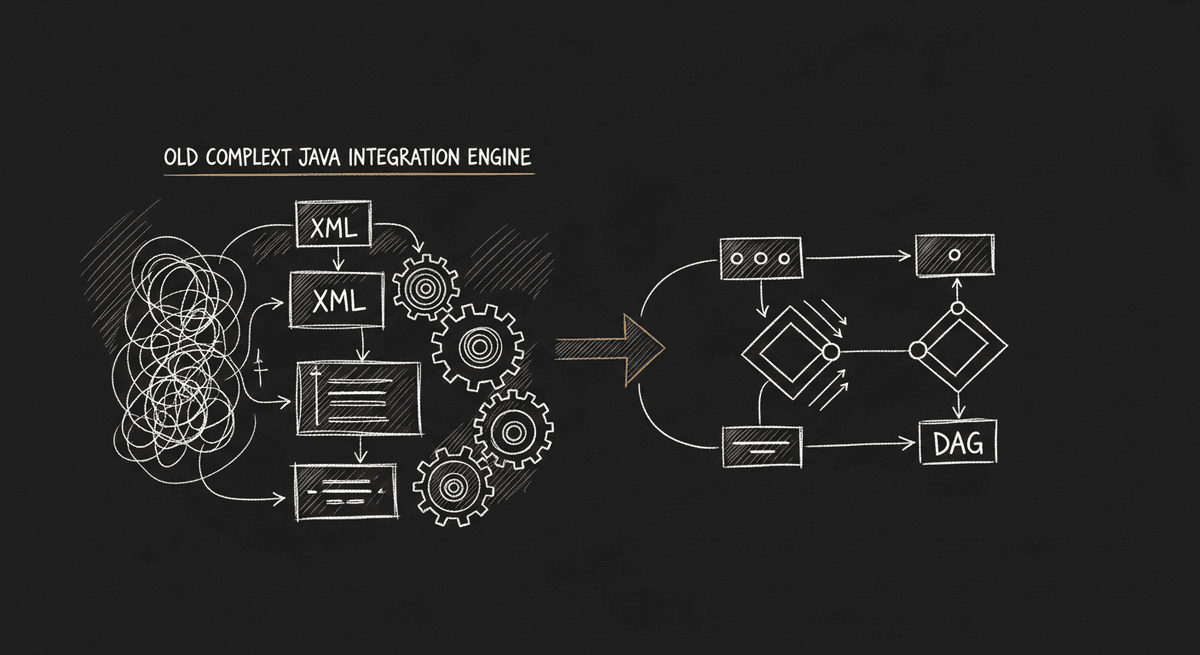 Healthcare integration8 min readMirth Connect, what happened? Here's What Comes Next.Mirth democratized healthcare integration. Then NextGen acquired it, and the world moved on. What the next generation of integration tooling looks like, and why the transition was inevitable.
 Applied LLMs & AI engineering8 min readProduct Evals in Three Steps (That You'll Actually Do)Most teams skip evals because the process feels overwhelming. The three steps that make eval-driven development achievable: label a small dataset, calibrate an LLM evaluator to human judgment, then iterate configs against the harness.
 Applied LLMs & AI engineering8 min readTable Stakes for Pragmatic Development Using LLMsUpdated for 2026: lessons from two years using Claude Code in production. Context engineering, real eval frameworks, model economics, and agent workflows. What works.
 Engineering leadership & career10 min readStaff Engineer Layoff Survival Guide: Lessons from 2008, 2020, 2023 — and NowI've survived three tech recessions. Lost my job in one, held the axe in another. The AI boom changed the rules again. The updated playbook for 2026.
 Engineering leadership & career9 min readThe Principal IC Playbook Nobody Shares With YouReaching principal is the first rung of a new ladder, not the last rung of the old one. What nobody told me about the ownership-autonomy paradox, how leverage works at this level, and the charter model I wish I'd had from day one.
 Frontend & React7 min readThe ESM Mess: JavaScript's Module System Is Still Broken and Here's WhyES Modules have been the supposed future of JavaScript for nine years. Only 9-27% of the ecosystem has adopted them. What's really going on, and how to survive until the ecosystem commits.
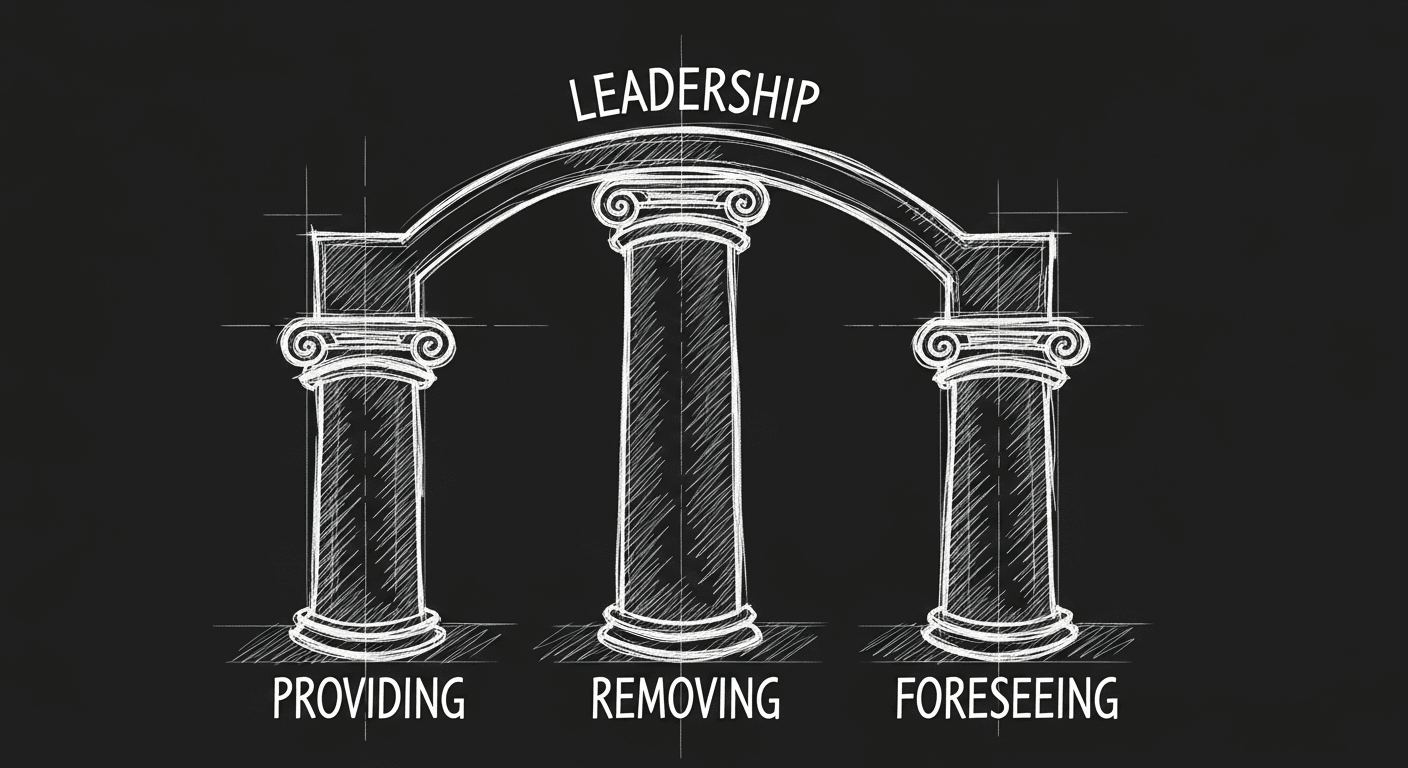 Engineering leadership & career7 min readThe Three Things Exceptional Engineering Leaders Do (And the One They Stop Doing)Most engineering leaders excel at one of three pillars and quietly fail at the other two. The three are: providing direction, removing obstacles, foreseeing change. What it takes to build strength across all three.
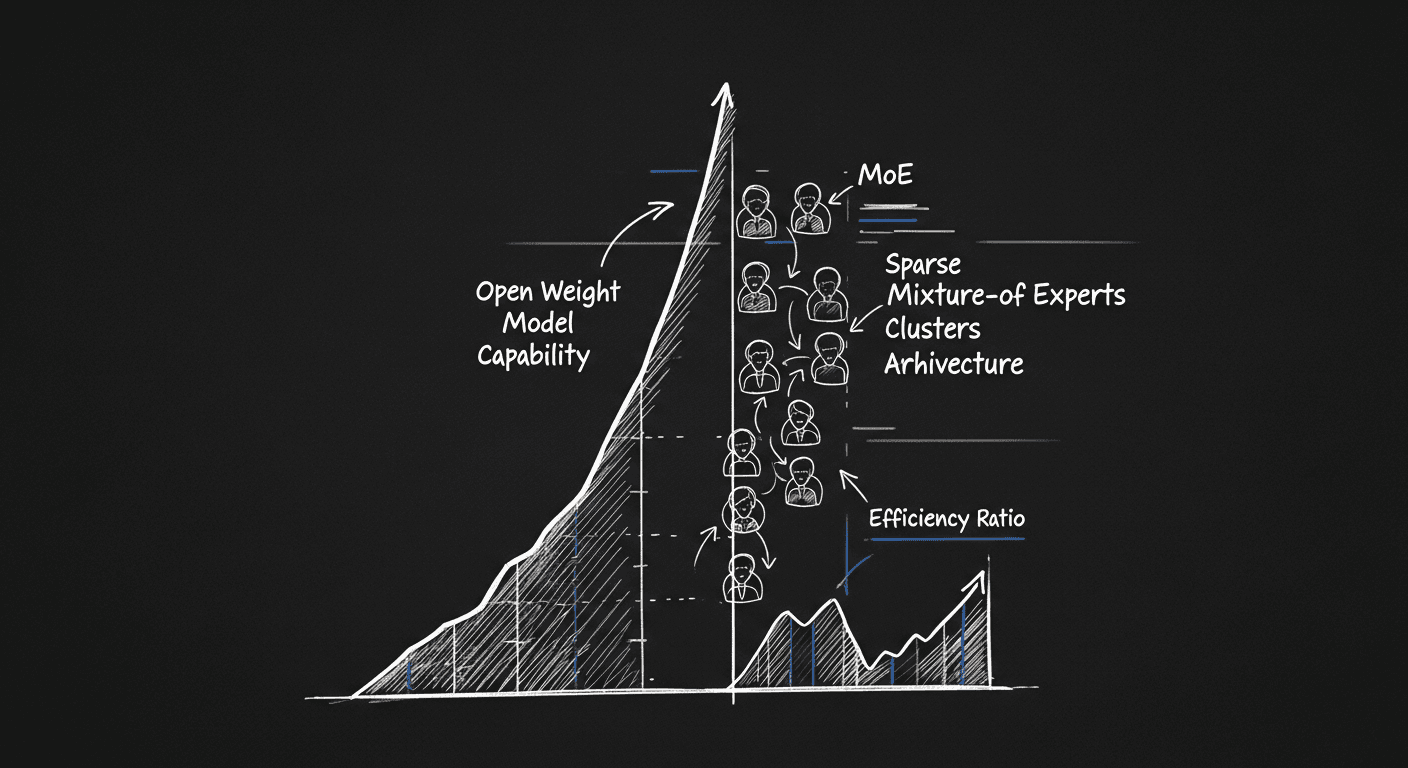 Applied LLMs & AI engineering8 min readThe Open-Weight LLM Landscape in 2026: What Engineers Actually Need to KnowThe open-weight ecosystem has matured faster than most engineers realize. MoE proliferation, hybrid attention, and extended context windows are changing what's deployable on-premise. That matters more than ever for healthcare AI.
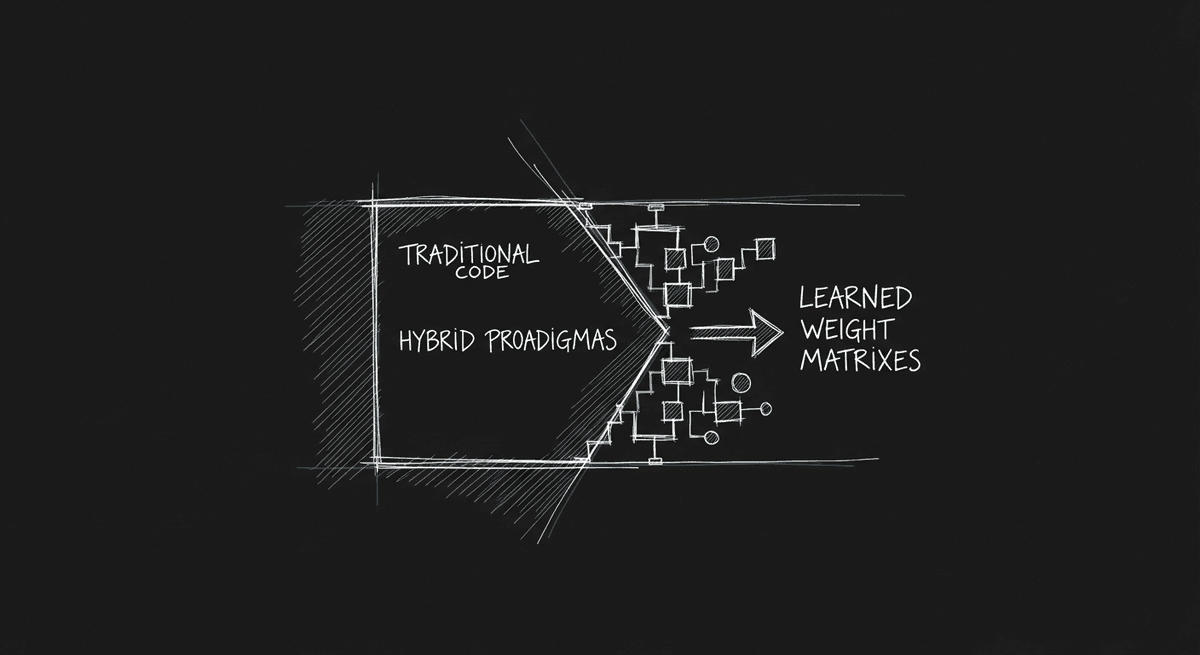 Applied LLMs & AI engineering7 min readSoftware 2.0 Is Here and It Changed How I Think About ProgrammingIn 2017, Andrej Karpathy argued that neural networks would replace explicit logic as the dominant programming paradigm. Nine years later, that prediction has fully landed. The implications for how we build software are bigger than most engineers want to acknowledge.
 Engineering leadership & career8 min readThree Ways to Know If Your Career Is Actually GrowingNormal career metrics: title, pay, team size. They tell you how you're doing relative to others. They don't tell you whether you're growing. Three metrics that do.
 Applied LLMs & AI engineering7 min readRAG Isn't Dead. You're Just Using It Wrong.The 'RAG is dead' narrative is wrong, but it's wrong in an interesting way. What kills LLM context quality in production, and what to do about it.
 Applied LLMs & AI engineering8 min readFine-Tuning a 70B Model on a Consumer GPU: The Q-LoRA Practical GuideQ-LoRA + SFTTrainer + Flash Attention v2 means you can fine-tune a 70B parameter model on 24GB of VRAM. What that looks like end-to-end, what it costs in quality, and when to just use the API instead.
 Engineering leadership & career7 min readTime vs. Timing: The Career Framework I Wish I Had EarlierI've made bets that paid off because of timing and bets that paid off because of compounding. Confusing the two is how careers stall.
 Applied LLMs & AI engineering8 min readThe LLM Year in Review: What Actually Mattered in 2025 (And What Was Noise)The prediction was: bigger models win. The reality was: DeepSeek R1 rewrote the rules in January and nothing was the same after that. What 2025 taught us about reasoning, inference-time compute, and the economics of intelligence.
2025
 Engineering leadership & career7 min readFrom Contractor to Consultant: The Mindset Shift That Changes Your IncomeContractors sell time. Consultants sell results. That distinction is the whole game. How I changed my pricing, positioning, and client selection once it clicked.
 Applied LLMs & AI engineering8 min readWhat the Teams Actually Shipping Coding Agents Have Figured OutCoding agents are the most economically viable AI in production today. The patterns Devin, Cline, Amp, and others converged on, and what they mean for anyone building or using agents seriously.
 Applied LLMs & AI engineering7 min readStop Shipping Features: Why AI Products Need an Experiment Mindset12 features shipped in a quarter. Zero meaningful metrics moved. AI products aren't software projects. The roadmap is a hypothesis board, not a delivery schedule, and treating it otherwise is expensive.
 Applied LLMs & AI engineering8 min readBeyond Chunks: Why Faceted Context Is the Future of RAGChunk-based RAG returns results. Faceted context gives agents peripheral vision: an understanding of the information landscape that lets them navigate rather than just consume. What that looks like in a domain where getting it wrong matters.
 Applied LLMs & AI engineering7 min readContext Engineering: The Skill That Replaced Prompt EngineeringPrompt engineering is a symptom, not a skill. The engineers shipping better agents aren't writing better instructions. They're designing better information spaces. Context engineering is the meta-skill no one teaches.
 Applied LLMs & AI engineering8 min readEvery Service Is Going to Need an MCP LayerREST APIs were designed for humans calling services through UIs. AI agents are not humans. What breaks when you expose your existing APIs to agents, and what the right architecture looks like.
 Applied LLMs & AI engineering7 min readWhen English Became a Programming Languagev0 just proved that English plus AI can replace traditional web development for most apps. That changes what it means to be a developer. An honest take on what shifts, what doesn't, and what to do about it.
 Applied LLMs & AI engineering8 min readFine-Tuning LLMs Without the RLHF Headache: The DPO ApproachRLHF is the right idea with the wrong implementation cost for most teams. DPO flips the math. How to align a healthcare AI model on clinician feedback without burning a month on reward model engineering.
 Engineering leadership & career9 min readAgency Beats Intelligence: How I Now Hire (And Evaluate Myself)Raw intelligence is abundant and cheap. The engineers thriving in the AI era are the ones with agency: setting goals, acting under uncertainty, self-correcting. How I changed my interview process to find them.
 Applied LLMs & AI engineering7 min readYou Are No Longer a Coder: The Shift from Execution to DirectionI stopped writing most of my own code. What changed, what I delegated to AI, what I found it can't do, and why the hardest part of the transition had nothing to do with technology.
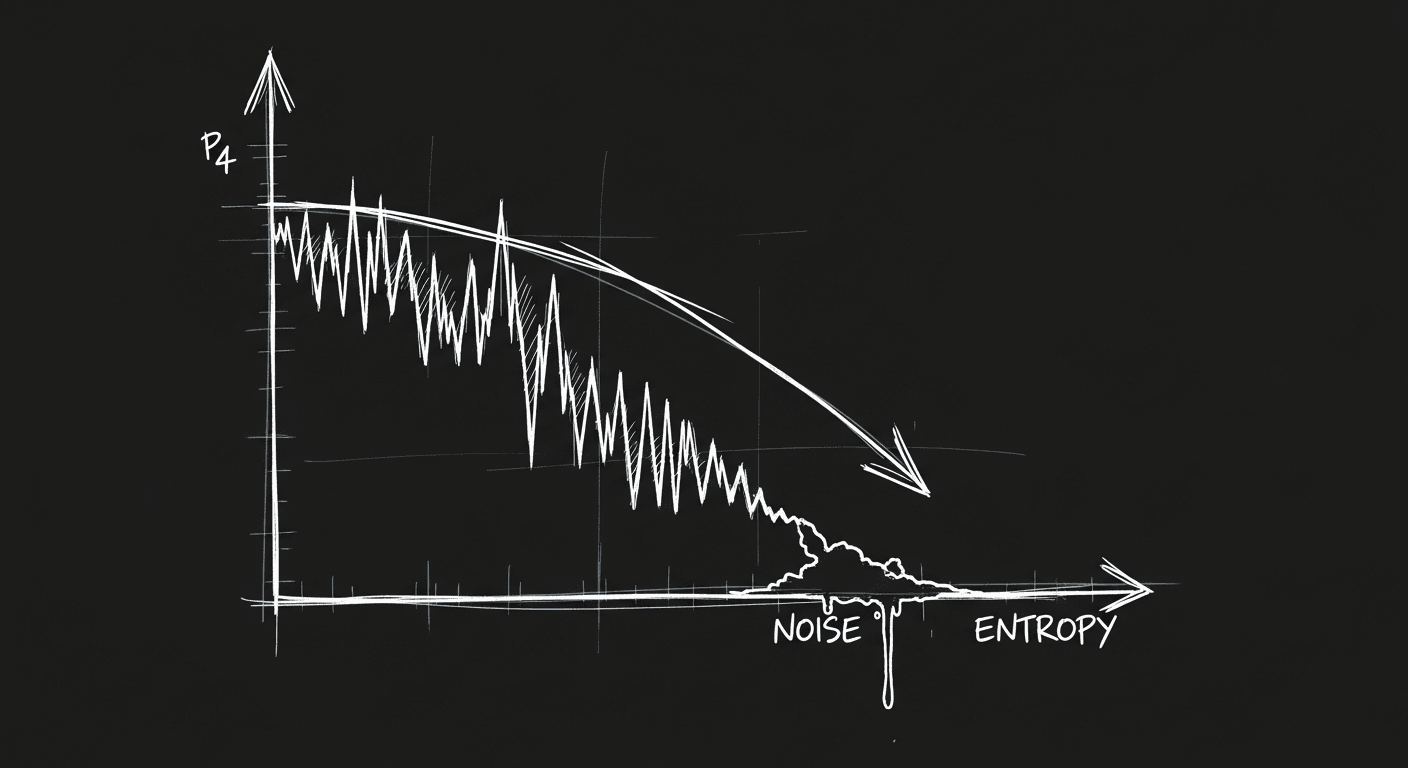 Applied LLMs & AI engineering7 min readContext Rot: The Silent Performance Killer in Your LLM ApplicationYour LLM system works great in demos and degrades in production. The culprit is almost never the model. It's what you're feeding it. How to diagnose and fix context rot before it kills your product.
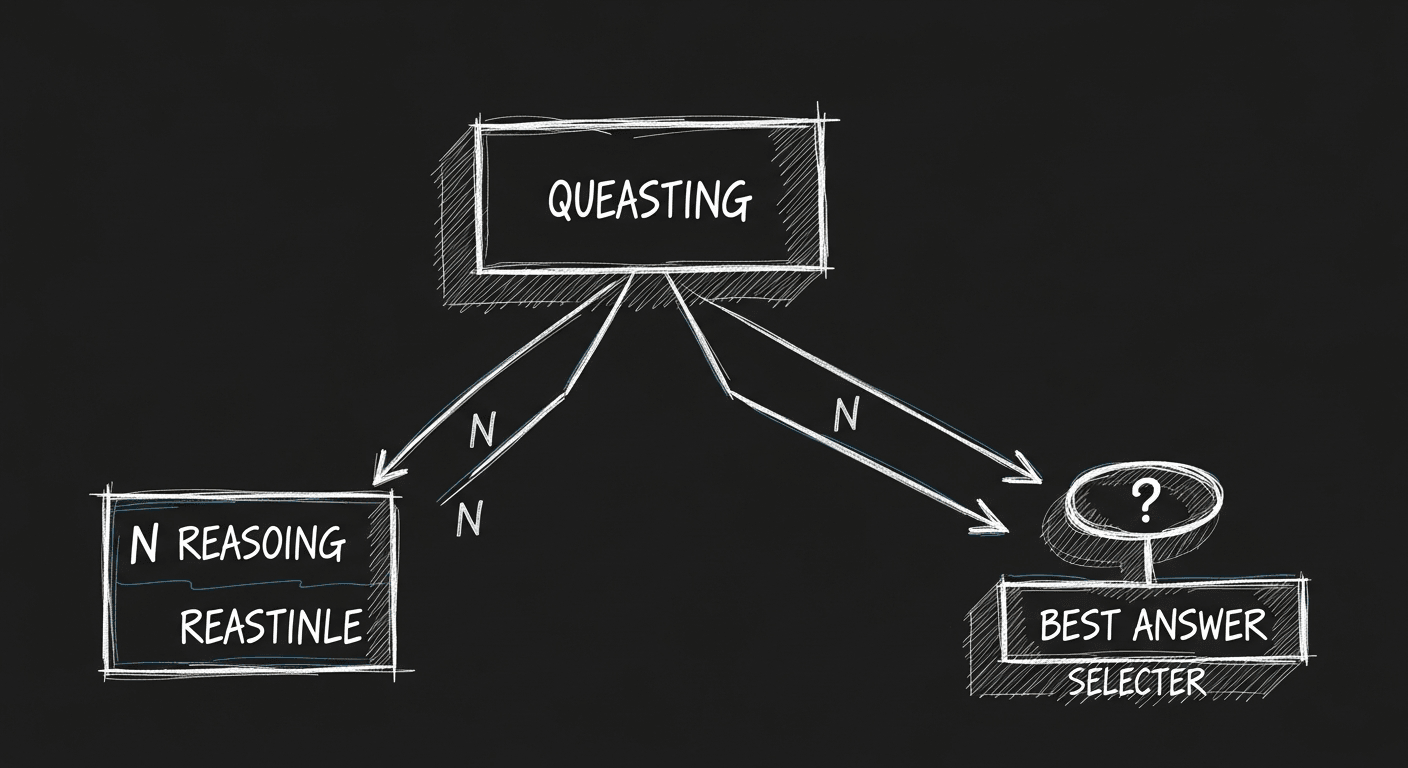 Applied LLMs & AI engineering8 min readWhy Your AI Gets Smarter When You Let It Think LongerTest-time compute is the most underused lever in production AI right now. What chain-of-thought, best-of-N sampling, and process reward models mean for practitioners, and when to use them instead of grabbing a bigger model.
 Engineering leadership & career8 min readThe Async-First Engineering Team: What Actually Works (And What Doesn't)I went async-first with my remote engineering team. Productivity went up. Culture took a hit. What changed, what broke, and the specific practices that made it worth it.
 Applied LLMs & AI engineering8 min readWhat the AI Tool Ecosystem Is Actually Telling YouTool selection in healthcare AI is a compliance problem, not a productivity one. Most AI tools that sounded great in 2023 are dead or deprecated. The framework I use for betting on the right ones.
 Applied LLMs & AI engineering7 min readWhat Autonomous Vehicles Taught Me About Multi-Agent AI DesignBAIR researchers discovered that just 5% autonomous vehicle penetration can smooth all highway traffic, with no central coordination. That finding reshapes how I think about building multi-agent AI systems.
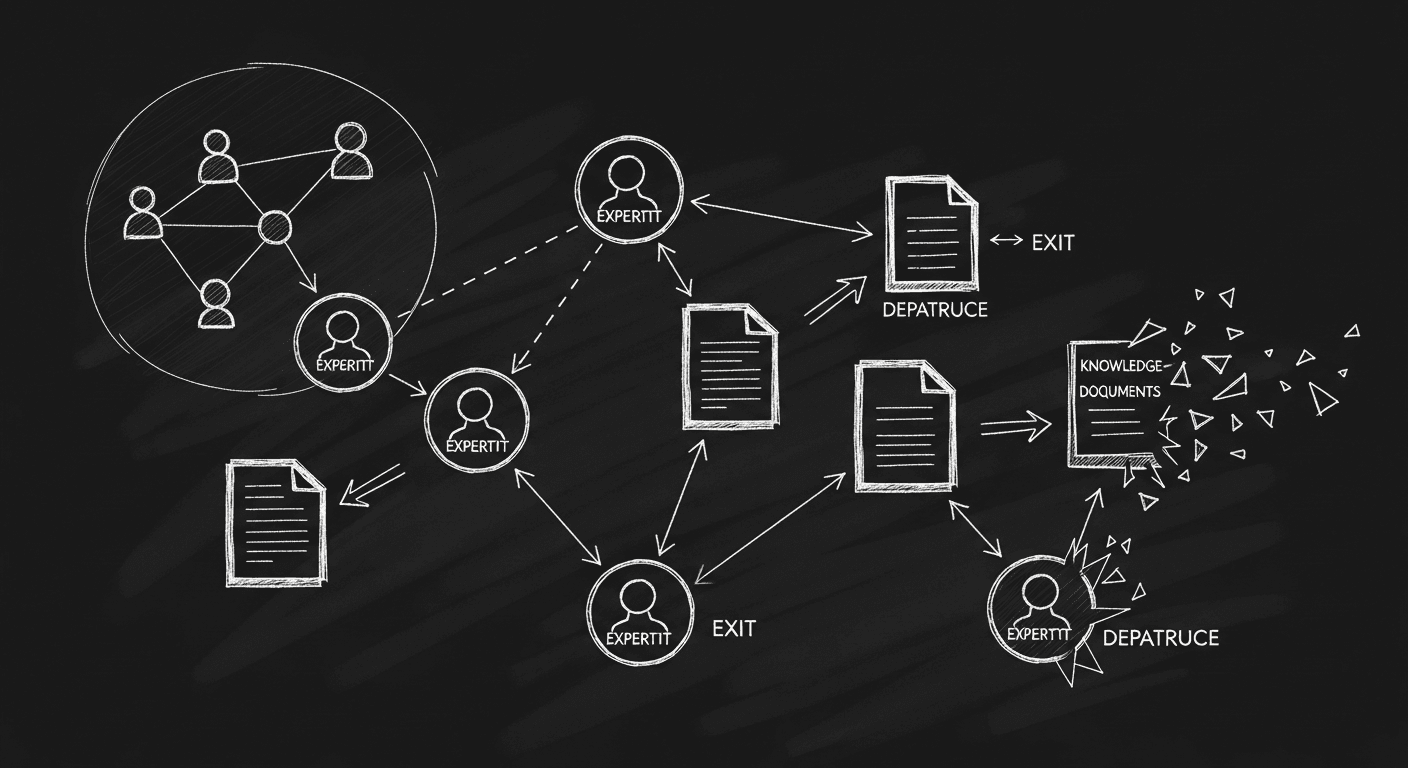 Engineering leadership & career7 min readThe Death of Institutional Memory: Why I'm Building Atlas (And Why It Matters)Every resignation takes a piece of the organization nobody wrote down. Org charts capture hierarchy, not the relationship networks that keep things running. A different approach to preserving institutional knowledge before it walks out the door.
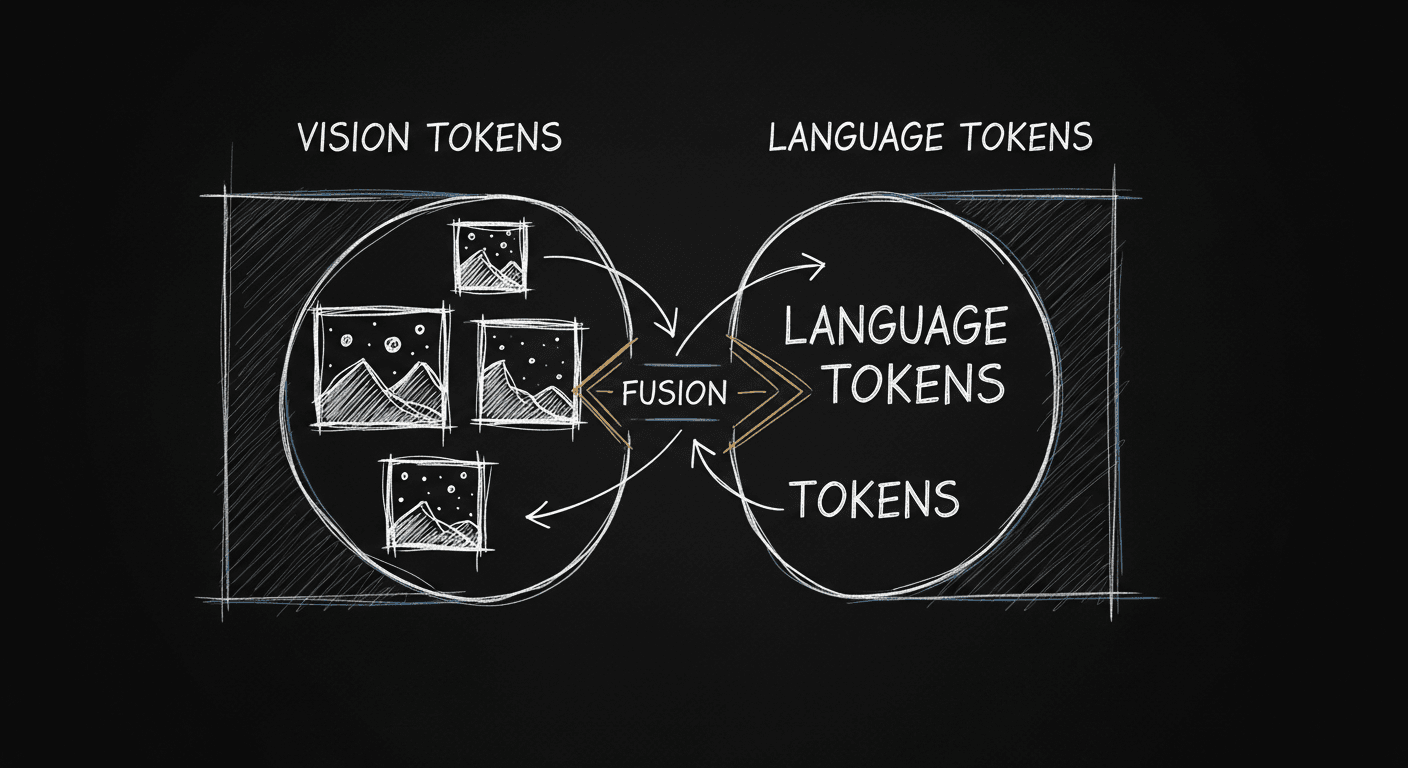 Applied LLMs & AI engineering9 min readVision + Language: How Multimodal LLMs Actually Work (And When to Use Them)Multimodal LLMs integrate vision through two fundamentally different architectures. Knowing which one you need, and why, shapes every other technical choice in your build.
 Applied LLMs & AI engineering8 min readThe Self-Healing Stack: What AI-Native Infrastructure Actually MeansThe AI Cloud vision, where infrastructure monitors, optimizes, and repairs itself, is compelling. Some of it exists today. Most doesn't yet. What self-healing infrastructure looks like in practice, and what engineers should be doing to prepare.
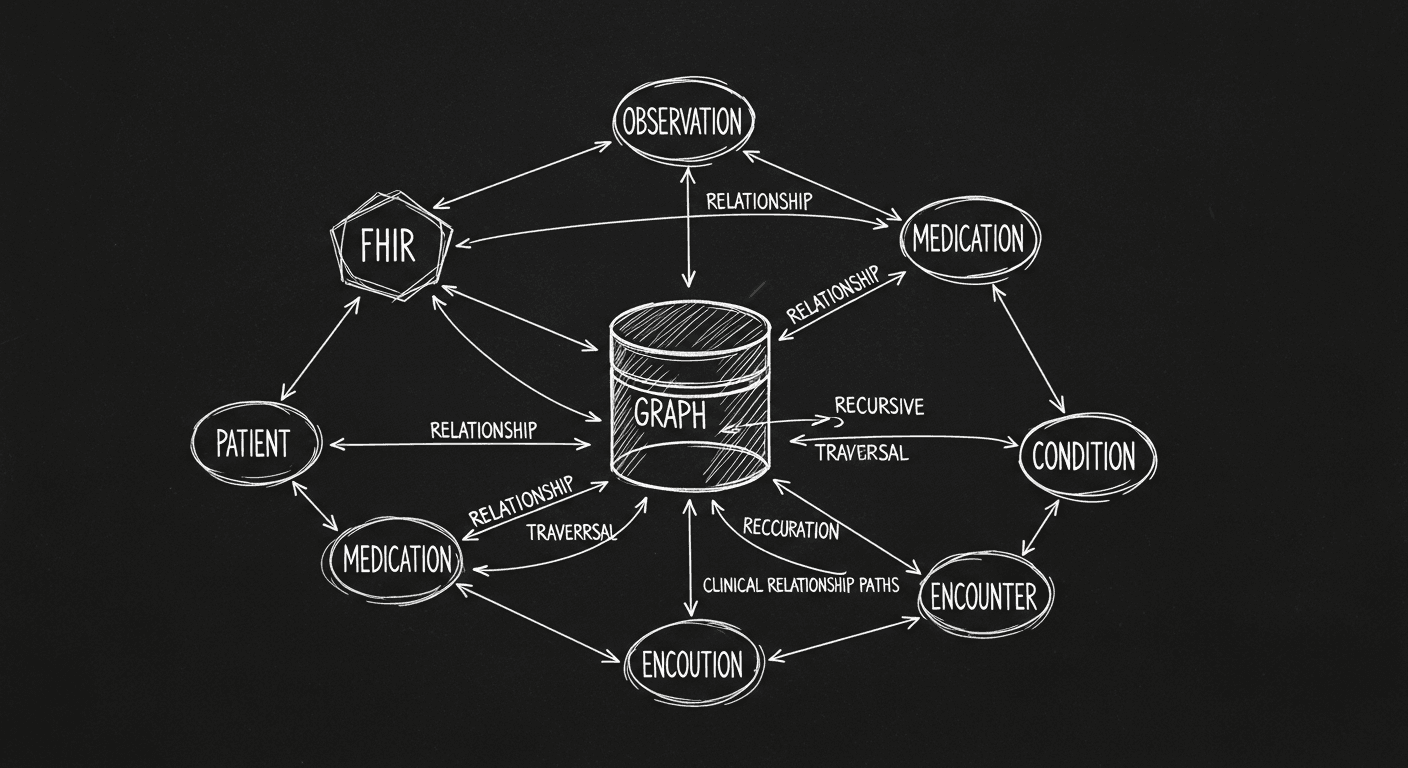 Healthcare integration12 min readFHIR Meets Graph Databases: Exploring Healthcare's Natural Network StructureFHIR data is a graph. Treating it as flat tables is why most healthcare AI struggles with relationships between patients, providers, and encounters. What happens when you model it the way it actually is.
 Applied LLMs & AI engineering7 min readThe Tools I Dropped When AI Changed My Development WorkflowAI coding assistants forced a full rethink of every layer of the dev stack. What I dropped, what I added, and the principle behind the restructuring.
 Applied LLMs & AI engineering8 min readFrom GPT-2 to DeepSeek: The Architectural Changes That Actually MatteredI've been reading ML papers for 10 years. Most don't matter. These architectural choices did. RoPE, GQA, SwiGLU: each one solved a real scaling problem. What to look for when a new model claims 'better architecture.'
 Applied LLMs & AI engineering8 min readBuilding a GenAI Platform That Doesn't Collapse Under Its Own WeightGenAI platforms don't fail because the models are bad. They fail because teams build everything at once. A practitioner's guide to layered architecture, from the minimal production-ready core to healthcare-grade guardrails.
 Applied LLMs & AI engineering8 min readThe GenAI Strategy Question You're Not Asking (But Should Be)Everyone asks 'how should we use GenAI?' The honest answer requires a harder question: does AI's unique capability create new value here, or is it just a more expensive way to do something that already worked? A practitioner's framework for getting this right in healthcare.
2024
 Applied LLMs & AI engineering7 min readEvery Failed AI Product Has the Same Root CauseThe same failure pattern shows up everywhere: teams shipping fast and iterating on vibes instead of building systematic evaluation. Evals aren't a nice-to-have. They're the core competency of any serious AI product team.
 Applied LLMs & AI engineering8 min readThe 6 Ways I've Watched GenAI Projects Fail (And How to Avoid Them)GenAI projects in healthcare go sideways in predictable ways, sometimes with real patient consequences. Six failure modes that come up over and over again, and what to do instead.
 Applied LLMs & AI engineering8 min readWhen to Look Beyond Standard LLMs (And When to Stop Overthinking It)Most teams should use a frontier API and move on. There are specific situations where alternative architectures matter: extreme latency, long-context scale, cost walls, privacy constraints. The decision framework.
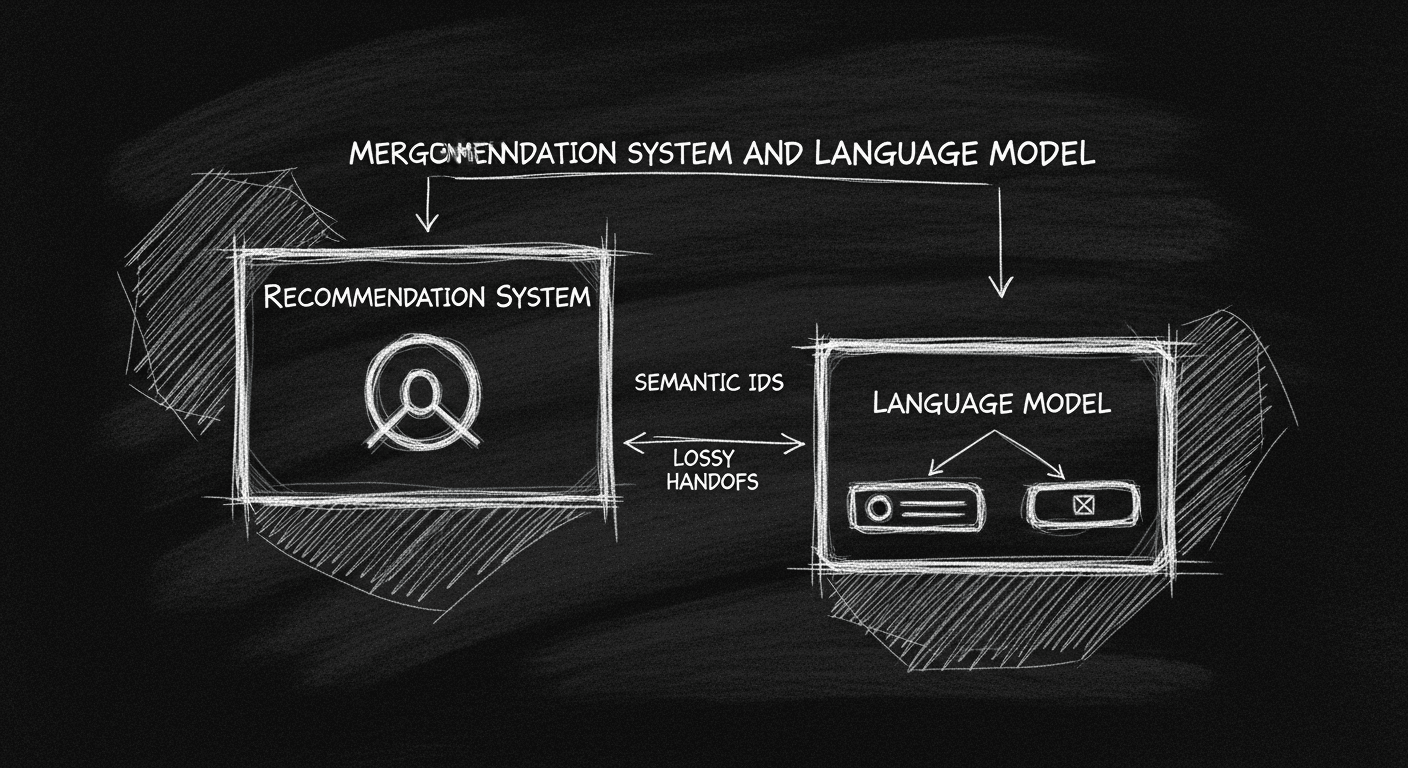 Applied LLMs & AI engineering7 min readWhen Recommendations Meet Language: The LLM-RecSys ConvergenceMost AI stacks treat the recommendation engine and the language model as two separate systems that hand off to each other. A new class of hybrid models eliminates that seam. The implications for domain-specific AI are significant.
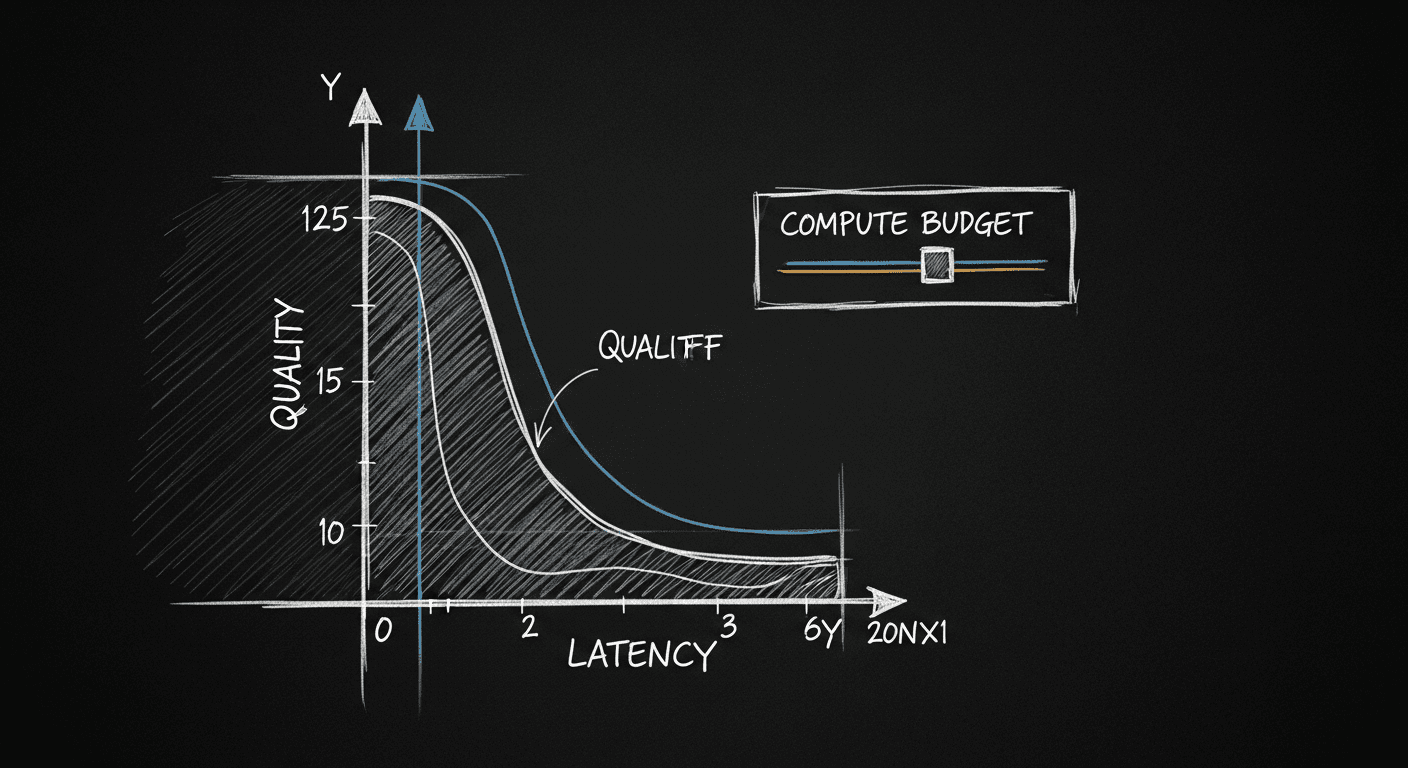 Applied LLMs & AI engineering9 min readTrading Speed for Quality: A Practical Guide to Inference-Time ScalingInference-time scaling lets you tune the latency-quality tradeoff at runtime instead of at training time. When to use Best-of-N sampling, beam search, iterative refinement, or one-shot generation, with real examples from clinical AI.
 Applied LLMs & AI engineering9 min readInside the Black Box: What Mechanistic Interpretability Means for BuildersHealthcare AI requires explainability. 'The model said so' is not a clinical rationale. Mechanistic interpretability is the research field trying to change that. What it offers practitioners today, where the gap is, and what to do in the meantime.
 Applied LLMs & AI engineering9 min readHow to Actually Test If Your AI Will Say Something DangerousMost teams treat jailbreak testing as a vibe check. StrongREJECT achieves 0.90 Spearman correlation with human judgment. Automated safety evaluation is real, and there's no excuse not to build it into your pipeline.
 Applied LLMs & AI engineering8 min readThe Attack Your LLM App Is Definitely Vulnerable ToPrompt injection is the #1 OWASP threat to LLM applications and most teams aren't taking it seriously. What the attack looks like, why it's hard to stop, and how to harden your system.
 Applied LLMs & AI engineering8 min readThe Honest Guide to LLM Evals: What Actually WorksMost teams skip real evals and wonder why their AI products degrade in production. The framework that holds up: from 30-minute manual reviews to binary scoring to knowing when your eval suite is finally doing its job.
 Healthcare integration6 min read5 Reasons to Solve for Adoption Before Building Your Digital Health ToolClinicians love the idea but no one's buying. That gap is a pattern, and it almost never comes down to the technology. Five adoption problems to solve before you build the product.
 Applied LLMs & AI engineering7 min readWhy Your LLM Evaluator Is Lying to YouLLM-as-judge evaluators feel like quality assurance but behave like rubber stamps. They fail hardest on the outputs that matter most: edge cases, safety-critical errors, domain-specific nuance. What to do instead.
 Applied LLMs & AI engineering6 min readWhy I Stopped Using RAG for Coding Agents (And What I Do Instead)The instinct when building a coding agent is 'I need RAG to handle large codebases.' The better instinct is giving the agent tools to explore code the way a senior engineer would: reading files, following imports, tracing execution.
 Frontend & React5 min readReact Tooling 2024: Stop Using the Wrong Shit20+ React apps built this year. What works, what's a waste of time, and why you're probably overengineering.
 Applied LLMs & AI engineering8 min readThe Neural Net Training Recipe That Actually WorksI spent months chasing architecture fixes when my real problem was bad debugging hygiene. The training recipe that works: start simple, visualize everything, tune last. The unglamorous discipline that separates working models from expensive experiments.
 Applied LLMs & AI engineering9 min readYou Don't Need GPT-4 for That: Small Models and Edge AgentsFrontier models aren't required for agentic function calling. For healthcare AI, assuming they are can also be a compliance liability. When a fine-tuned 7B model is the right architecture, and when it isn't.
 Applied LLMs & AI engineering8 min readMulti-Agent Orchestration in Practice: What I Learned Building Parallel Agent SystemsThe orchestrator/worker pattern is the key mental model for multi-agent systems. How to structure orchestrators, spawn and manage workers, aggregate results, and avoid the coordination failures that sink most implementations.
 Applied LLMs & AI engineering8 min readWhat It Actually Takes to Build a Real LLM AgentEveryone's talking about agents. Few have shipped one that works in production. The failure modes, memory tradeoffs, and tool design decisions the architecture papers skip.
2023
 Applied LLMs & AI engineering8 min readThree Hard Truths About LLMs in Production Nobody Warned Me AboutTwelve years in ML and I still got burned. Stochasticity is a systems design problem. Your target model will be deprecated. Silent failures are worse than loud ones. What production healthcare AI taught me.
 Applied LLMs & AI engineering6 min readWhat AI Agents Actually Are (And What They Can't Do Yet)Everyone's building 'agents.' Most are just APIs with a system prompt. The precise definition, the components that matter, the failure modes I've hit, and how to pick the right pattern for your problem.
 Frontend & React7 min readStop Using Optional Props: Why Discriminated Unions Make Better React ComponentsOptional props feel flexible until they ship a runtime error to production that TypeScript should have caught at compile time. The pattern that prevents it.
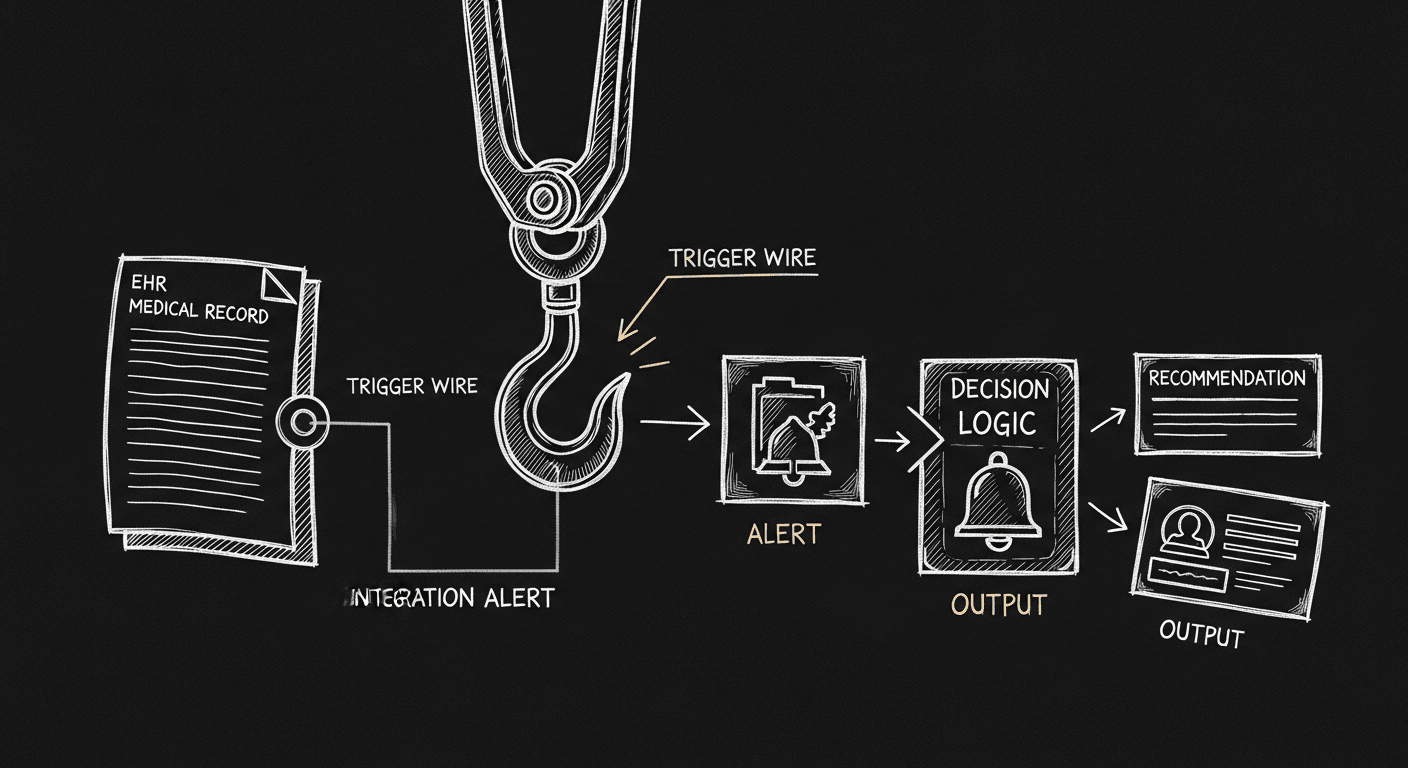 Healthcare integration4 min readCDS Hooks: What Nobody Tells You Before You BuildCDS Hooks look straightforward until you try to get them working in Epic. Six months of integration reality the documentation glosses over.
 Engineering leadership & career6 min readThe Food Truck Method: Building MVPs That Don't SuckMost MVPs turn into dumpster fires not because teams move too fast, but because they move fast in the wrong direction. The food truck method for building without the regret.
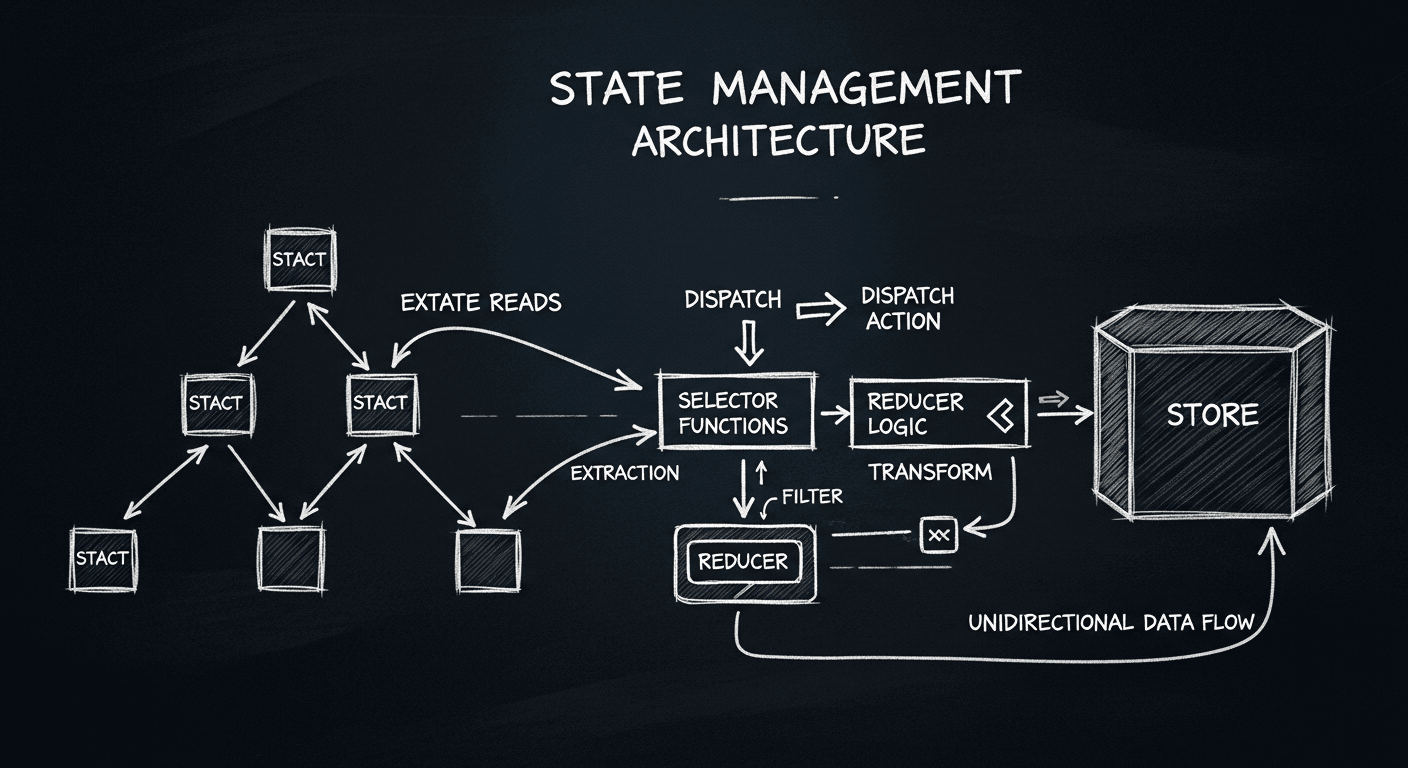 Frontend & React9 min readReact State Management & Clean SPA ArchitectureRedux, Zustand, Recoil, Context API. Most React apps use the wrong one for the wrong reasons. What each tool is for, when SSR changes the calculus, and how to pick without a fight.
 Healthcare integration10 min readHIPAA Consent: What Engineers Actually Need to KnowHIPAA documentation runs to thousands of pages. What engineers building healthcare apps need to know, and what's compliance theater.
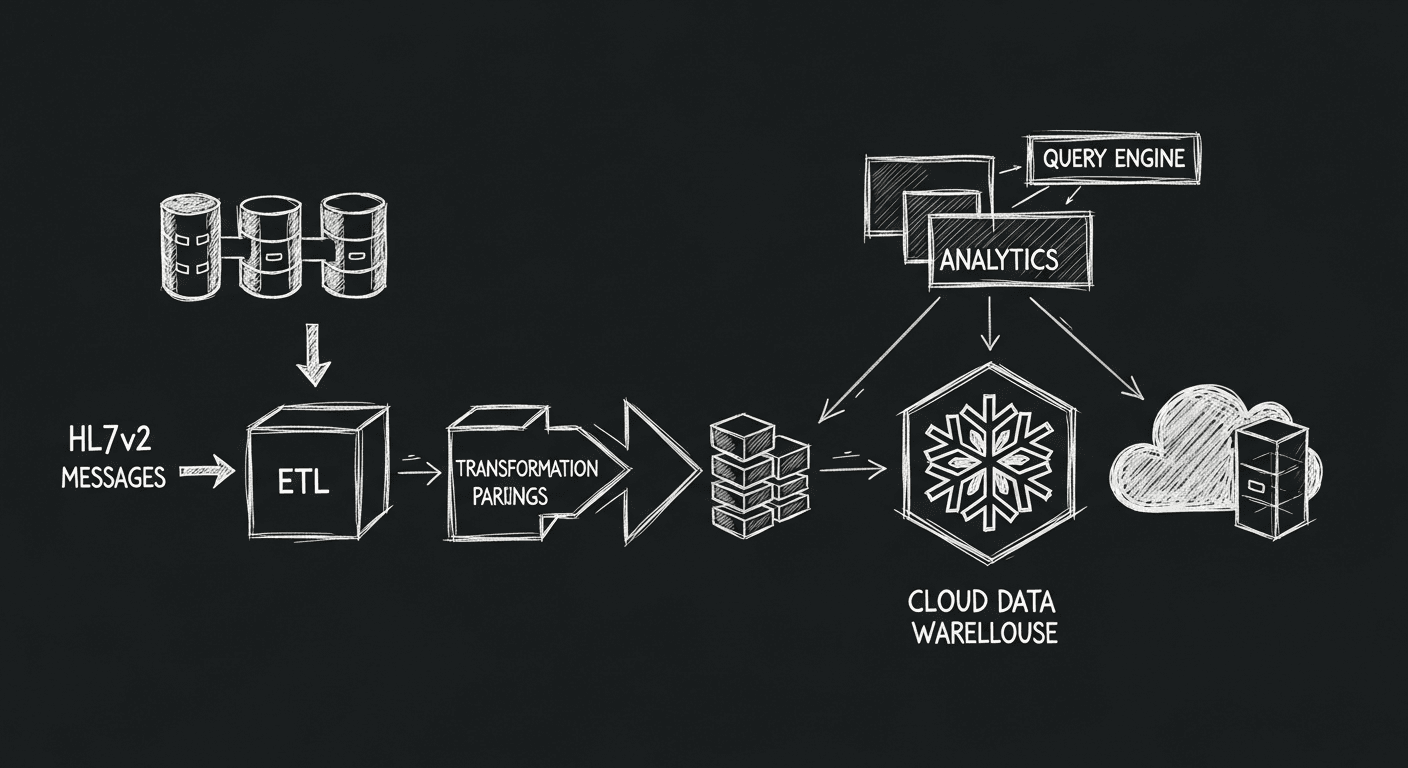 Healthcare integration8 min readIngesting HL7v2 with ❄️ Snowflake Part 1Snowflake's flexible compute model makes it interesting for healthcare data warehousing. A walkthrough for ingesting HL7v2 messages into Snowflake: schemas, parsing, and getting clinical data into a structure you can query.
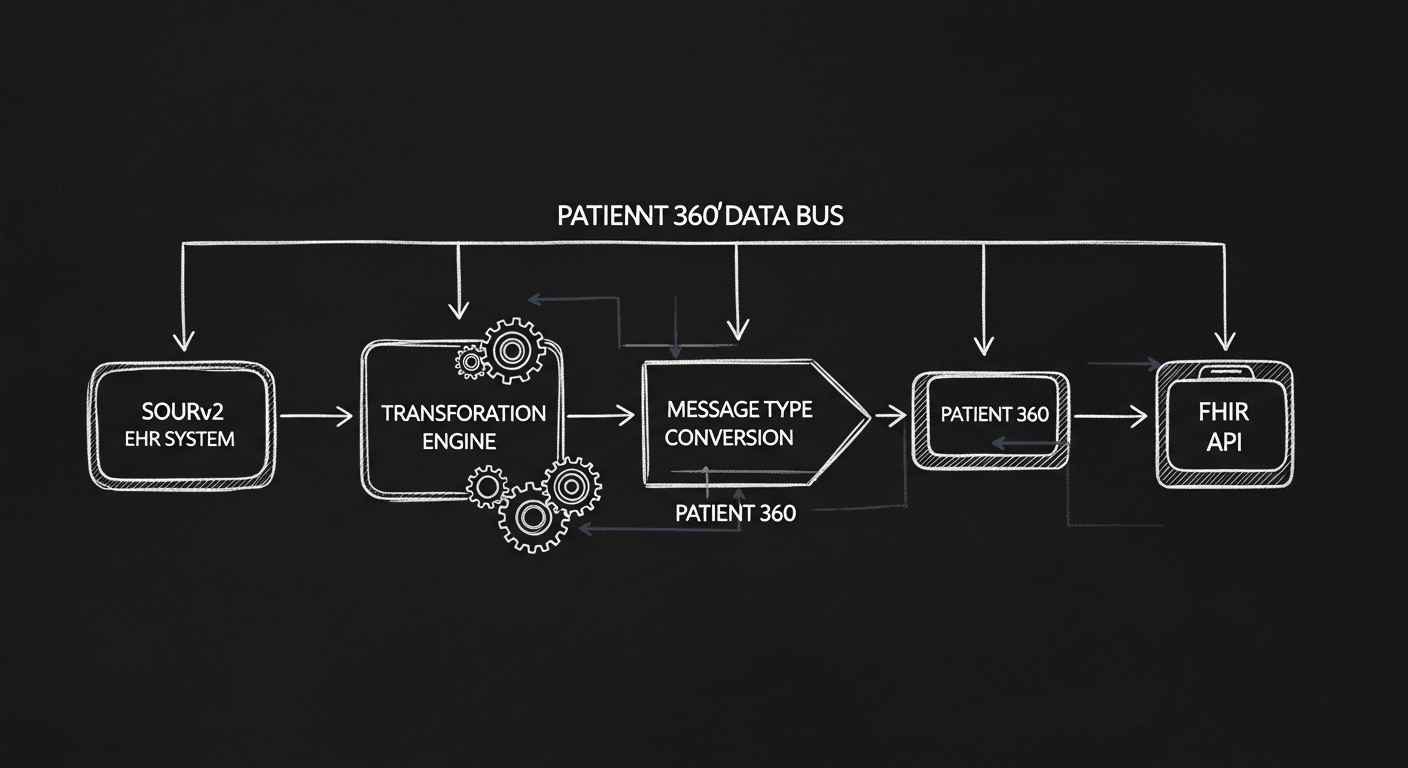 Healthcare integration7 min readHL7v2 Healthcare Integrations with 🫏 MulesoftThe MuleSoft Accelerator promises a unified patient view across EHRs using FHIR and HL7v2 integrations. What that looks like in practice, where it delivers, and where you'll spend your consulting budget.
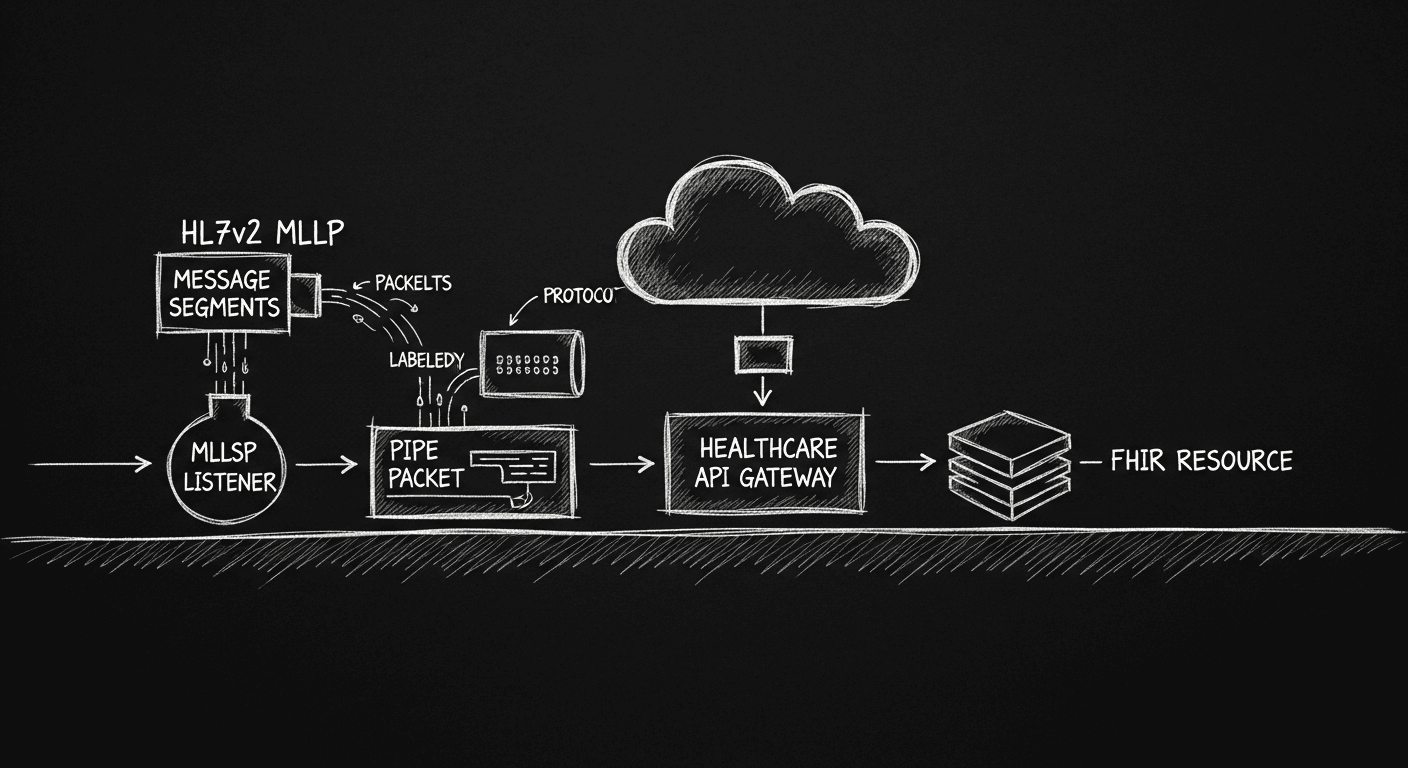 Healthcare integration11 min readHow to ingest HL7v2 Messages into Google CloudHL7v2 arrives over MLLP. Google Cloud Healthcare API converts it to FHIR. A complete walkthrough for capturing healthcare messages in Google Cloud, from DICOM stores to Pub/Sub triggers.
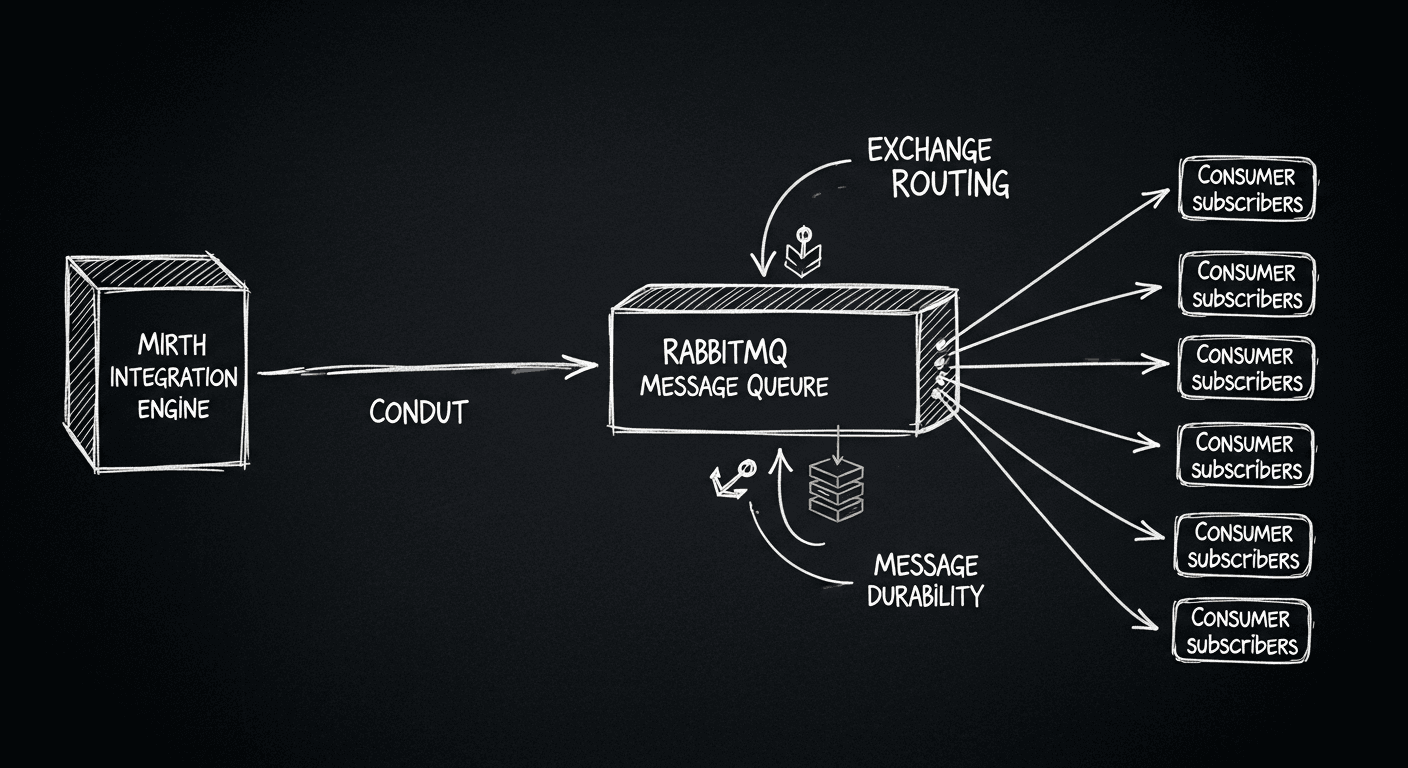 Healthcare integration5 min readMirth Connect: Part 2 - Adding 🐰RabbitMQMirth Connect handles the transform. RabbitMQ handles the delivery. Together they make healthcare integrations durable and survivable when downstream systems go down. How to wire them up.
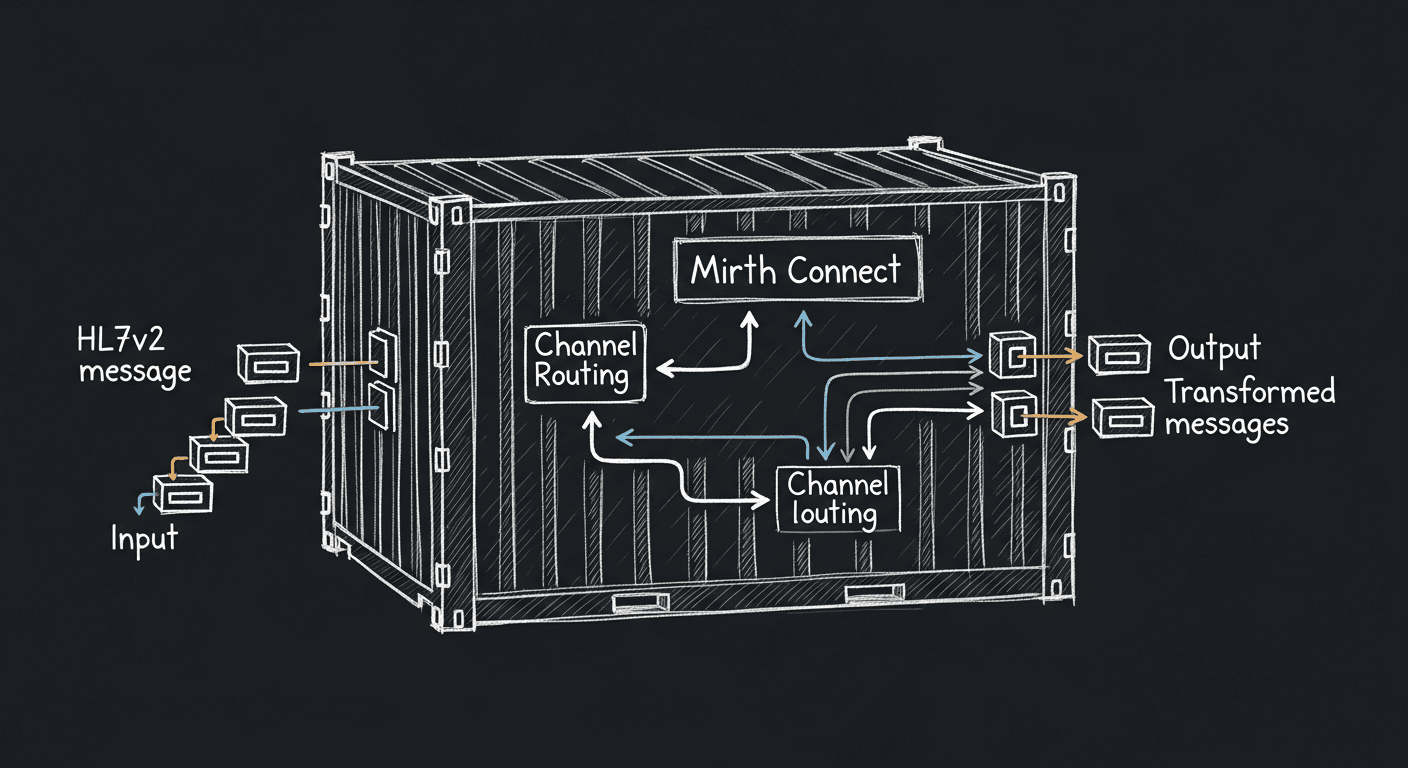 Healthcare integration6 min readMirth Connect: Part 1 - Getting Started with 🐳 DockerMirth Connect is how most healthcare orgs still move HL7v2 messages. Setup from scratch: configuring channels, parsing message types, sending and receiving messages without losing your mind.
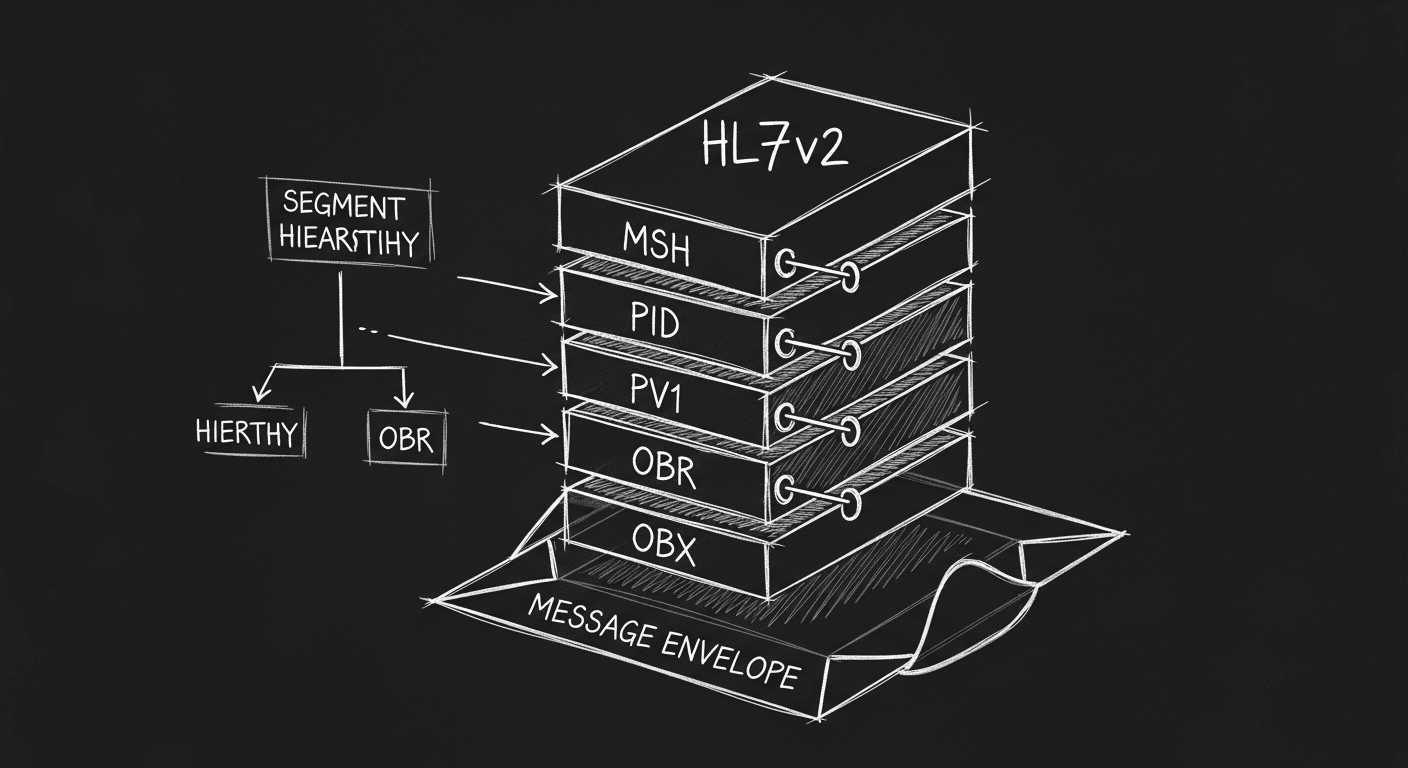 5 min readHealthcare Integration For Beginners: HL7v2HL7v2 is how most hospitals have moved clinical data for 30+ years. How it works, why it's still everywhere despite being a 1980s standard, and what you need to know before you start integrating.